What Gets Reviewed
This page explains what lgtmaybe looks at, how it bounds the work, and what the output looks like on a pull or merge request and on the command line. Each kind of check below is a lens: one focused review question for the model.
What It Looks At
lgtmaybe reviews the diff of a pull request (or a GitLab merge request): the lines it adds or changes, not the whole repository. It fetches that diff from your code host's REST API and never checks out or runs the PR's code. A malicious change therefore can't execute anything in the reviewer's environment. lgtmaybe treats the diff as untrusted input throughout, including against prompt-injection attempts hidden in PR text.
To review changes in context, lgtmaybe also pads each changed
hunk with surrounding lines read from the
head revision of the changed file. The model uses them to understand the change
(the enclosing function, nearby definitions) but only comments on changed lines.
The padding is budget-scaled and capped by context_lines (default 20, 0
disables it). lgtmaybe fetches it read-only via the API and
redacts it like the diff.
Before the diff reaches the model it is cleaned:
- Non-reviewable files are skipped: lockfiles, minified assets and
sourcemaps, vendored and build-output directories (
vendor/,node_modules/,dist/,build/,third_party/), generated code (protobuf output,.d.ts, Dart.g.dart, test snapshots), generated LLM-index corpora (llms.txt/llms-full.txt), and binaries. Reviewing them is noise and wastes tokens. - Oversized files are skipped: a single file whose diff runs past
max_file_diff_lines(default 2000,0disables) is dropped and named in the summary. Name matching only catches generated files whose name admits it; a hand-named 154,000-line data blob is caught on size alone. - Secrets are redacted: anything that looks like a key, token, private key or credential is stripped from the diff before it leaves your environment for the provider.
By default lgtmaybe also runs any installed static-analysis tools, such as
ruff, bandit, gitleaks and semgrep, over the changed files
(static-analysis fusion).
They run locally in a sandbox with no network. Their results go to the model as
redacted hints to confirm, put in context, or discard, so a tool's raw output
is never posted. A tool you opt into finding mode posts directly instead; see
static_analysis.
Correctness & Logic
The model is prompted to hunt for the bugs a change introduces and grade them by impact:
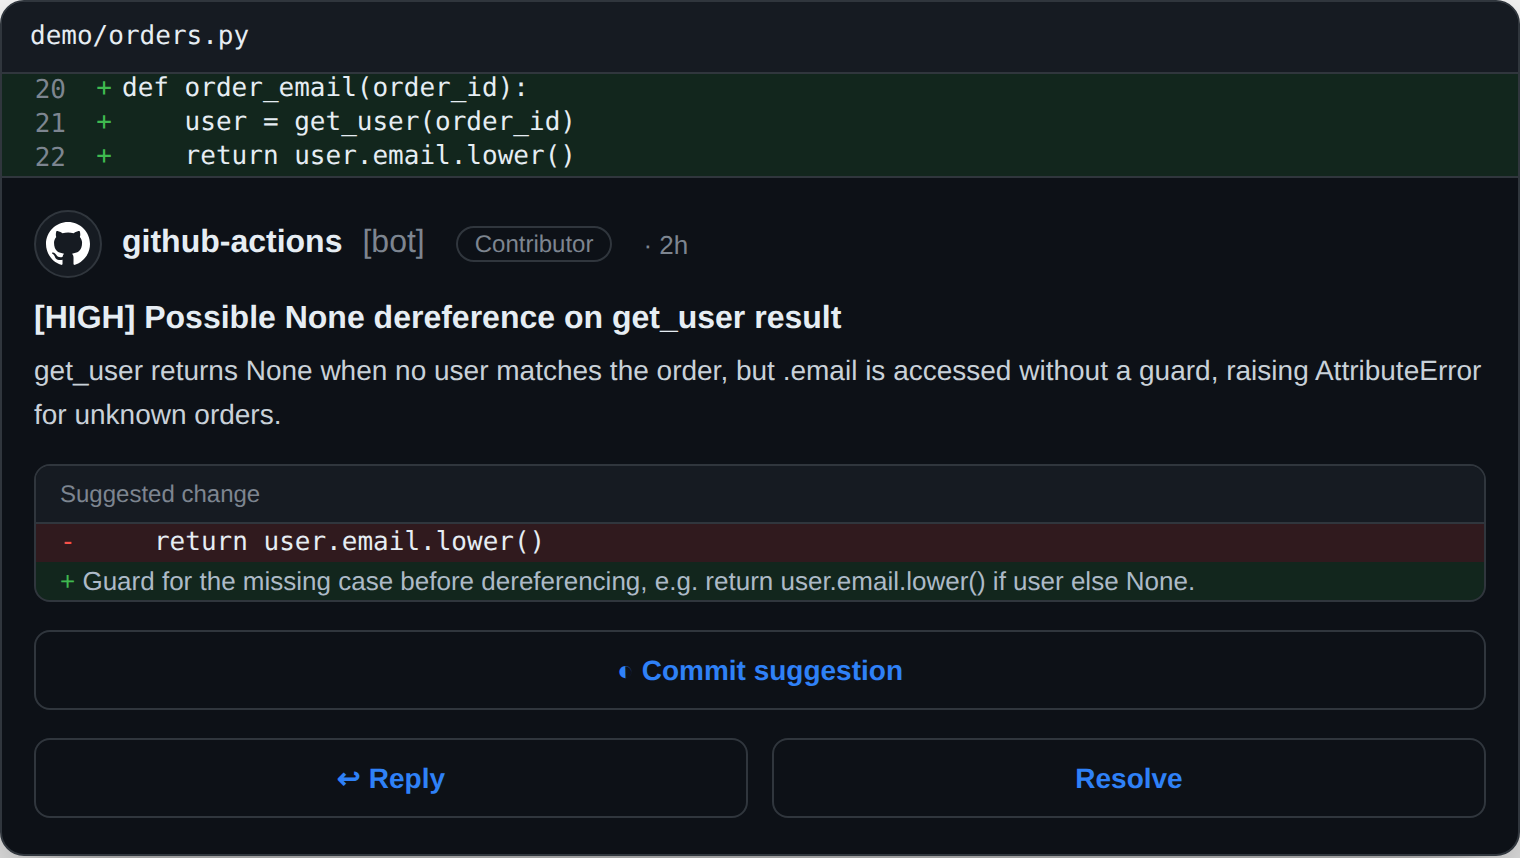
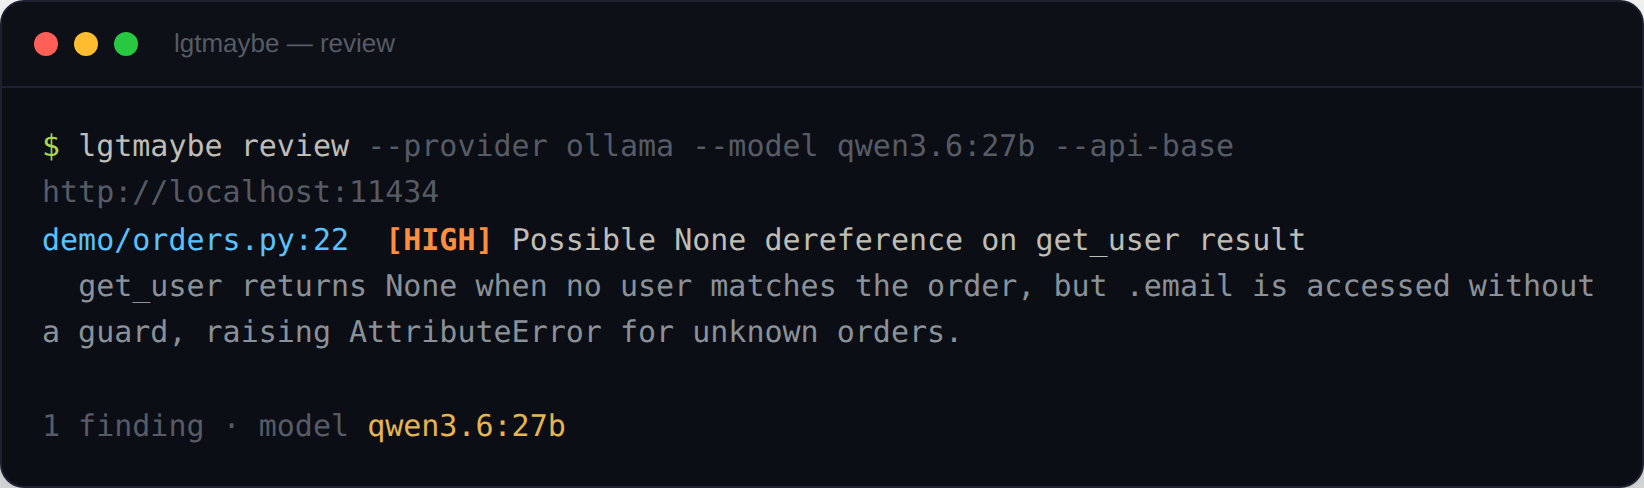
- Null / None dereferences: a value that can be empty used without a guard.
- Off-by-one and boundary errors:
<vs<=, fencepost mistakes, empty- and single-element edge cases. - Mismatched or inverted ranges:
start/endswapped, a lower bound above its upper bound. - Unhandled error and exception paths: failures silently swallowed, or state left half-updated.
- Incorrect conditionals: inverted booleans,
and/ormix-ups, missing branches. - Resource leaks and ordering: handles or locks not released, use-after-close, bad concurrent sequencing.
- Races and concurrency: check-then-act (TOCTOU), shared mutable state
without synchronisation, coroutines called without
await, blocking calls in async paths. - Numeric and date/time bugs: overflow, float equality, division by zero, money in binary floats; timezone-naive datetimes, epoch-unit confusion, DST.
- Aliasing and mutation: mutable default arguments, mutating a collection while iterating it, sharing a mutable value the caller still owns.
Security Review
The model is prompted with an OWASP-aligned checklist and told to grade what it
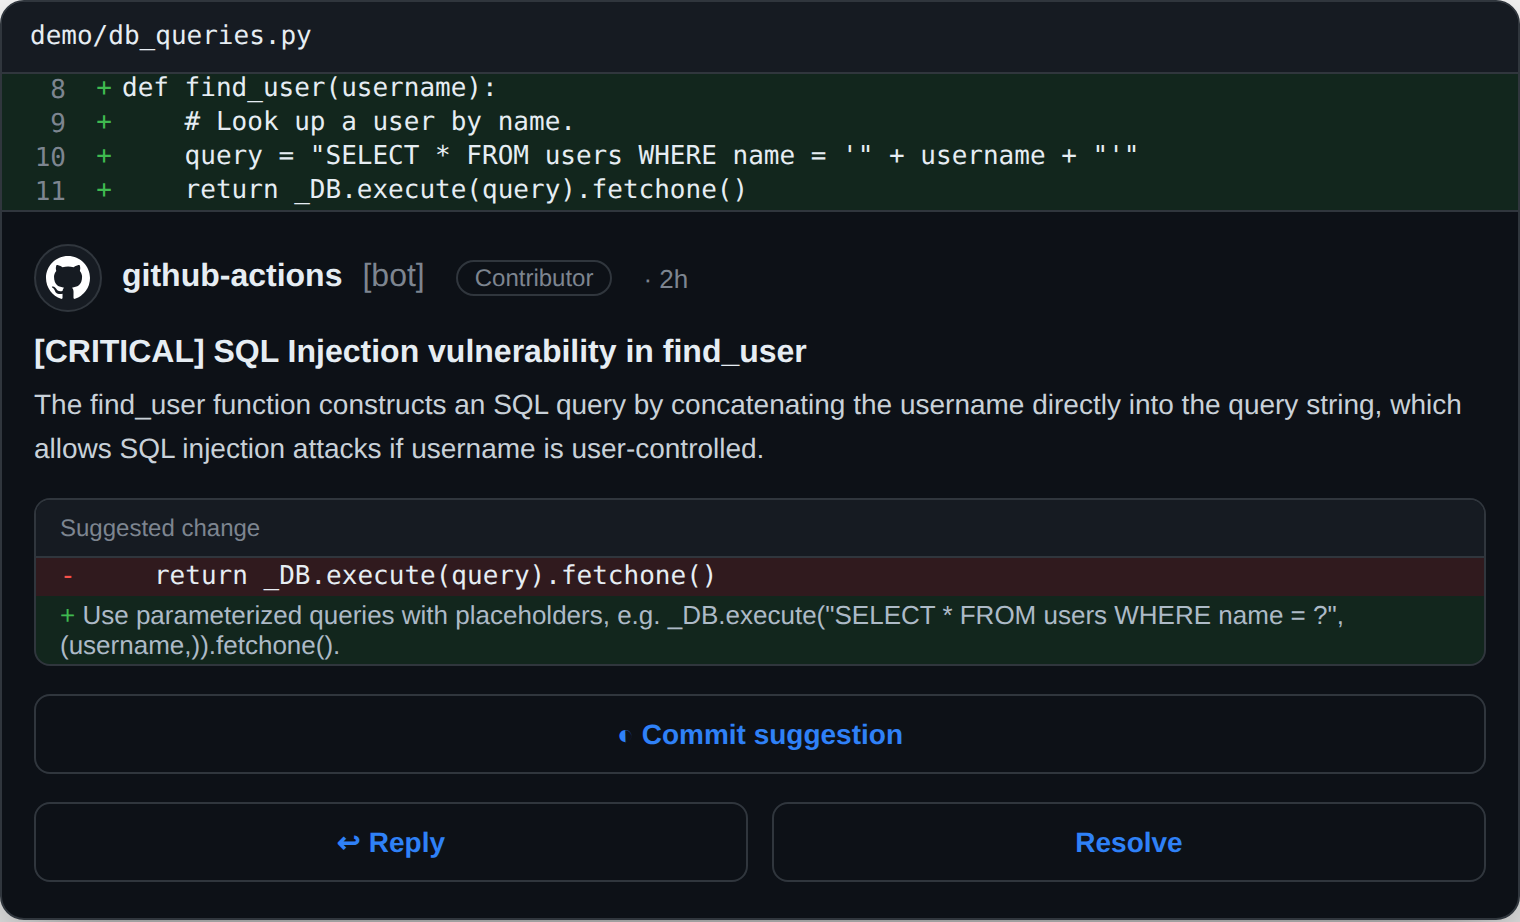
finds high or critical and name the vulnerability class in the title. It
looks for:
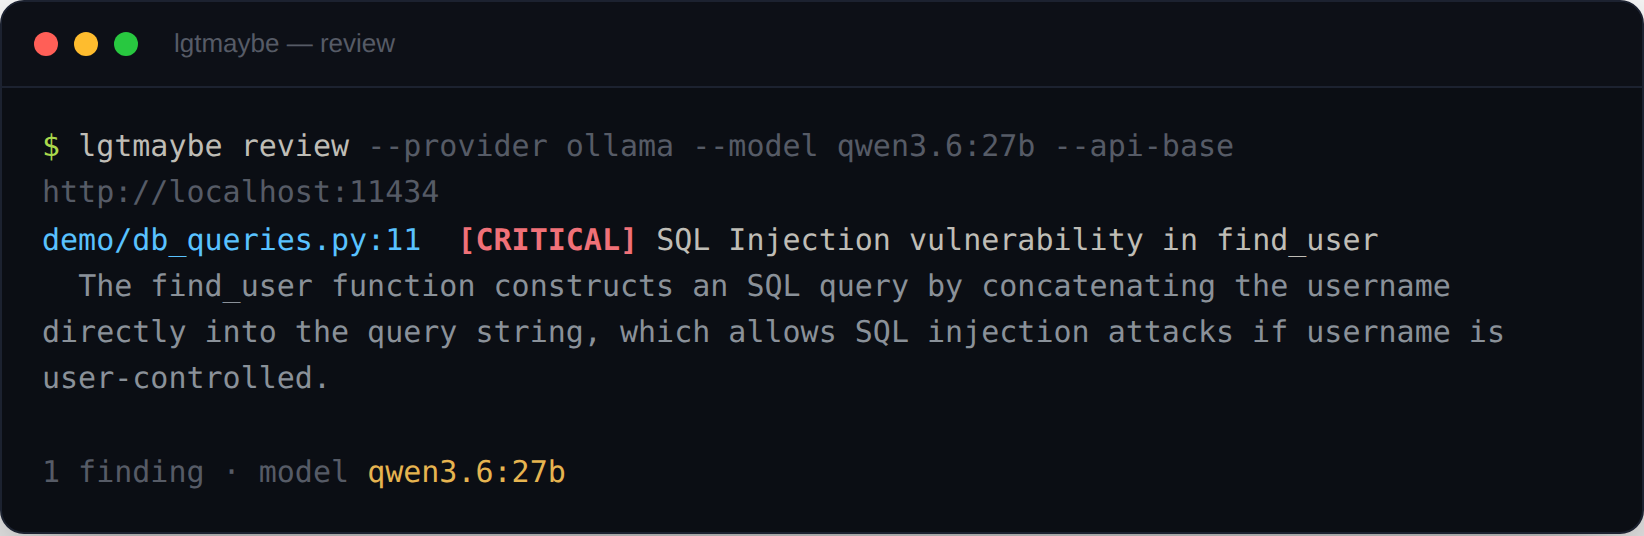
- Injection: SQL/NoSQL, OS command, and template/LDAP injection.
- Cross-site scripting (XSS): unescaped user input rendered into HTML/JS.
- CSRF and open redirect: unprotected state-changing endpoints, user-controlled redirect targets.
- Hardcoded secrets: keys, tokens, passwords, or private keys in the diff.
- Broken authn / authz: missing permission checks, IDOR, auth bypass, and
JWT or session pitfalls (unverified signatures,
algconfusion, missing expiry). - Path traversal and unsafe file access: user input in file paths,
../, zip-slip extraction, and unrestricted file uploads. - SSRF: server-side fetches of user-controlled URLs without allow-listing.
- Insecure deserialisation and unsafe eval:
pickle/yaml.load/evalon untrusted data, and XML parsed with external entities enabled (XXE). - Mass assignment / over-posting: request bodies bound straight onto models.
- Weak cryptography: MD5/SHA1 for passwords, ECB mode, disabled TLS verification, predictable randomness for security tokens.
- Sensitive-data exposure: secrets or PII in logs, error responses, or analytics (passwords, API keys, tokens/session IDs, SSNs, payment-card data).
- CI / IaC (infrastructure as code) misconfiguration: untrusted input
interpolated into workflow
run:steps, third-party actions not pinned to a SHA, overly broad IAM policies, public buckets, privileged containers, secrets echoed into build logs. It also flags:- controls that only look enforced, such as an
environment:key used as an approval gate when the environment has no required reviewers, or a budget alert treated as a spending cap; - checks that cannot fail, such as
continue-on-error: trueor|| trueon a test or scan step. A skipped check that reports a pass is worse than no check.
- controls that only look enforced, such as an
- Resource / DoS safety: missing timeouts, unbounded loops or allocations, regexes vulnerable to catastrophic backtracking (ReDoS).
This shapes what the reviewer flags. How lgtmaybe protects itself from a malicious PR (secret redaction, prompt-injection defence) is covered in Data and Privacy.
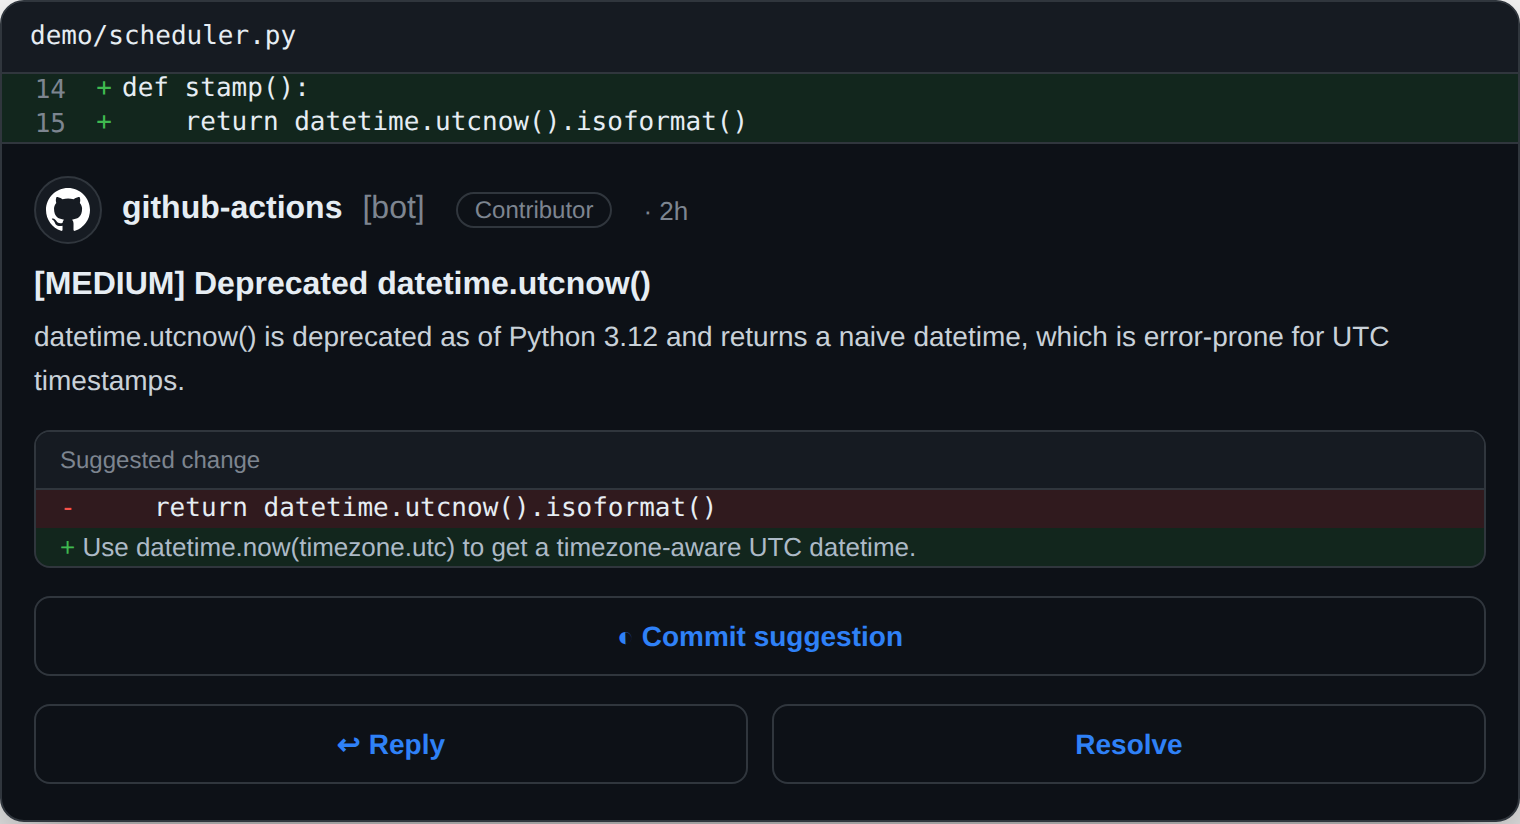
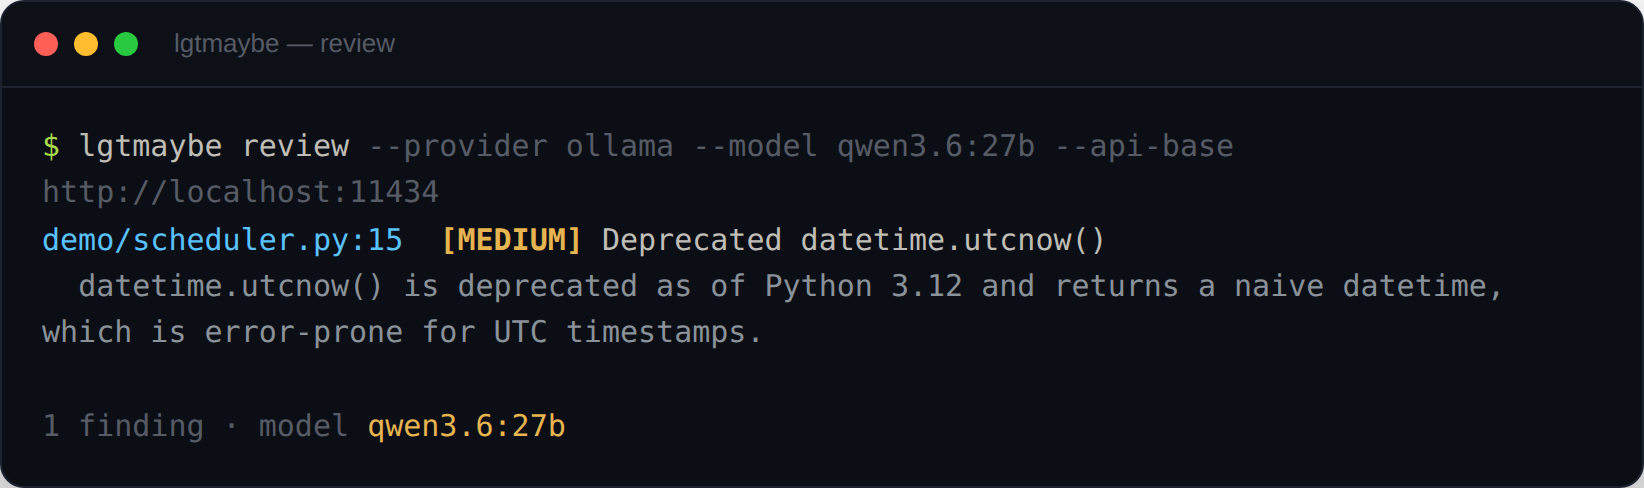
Deprecation & Dependency Health
The reviewer also flags factually outdated code when the diff shows it. These are objective, not stylistic:
- deprecated language or framework APIs (with the modern replacement when known),
- targeting an end-of-life runtime or language version,
- adding or pinning an end-of-life or abandoned dependency,
- pinning a dependency to a version with a known security advisory, and
- a new dependency whose name looks like a typosquat of a popular package, or whose licence conflicts with the project's.
It raises these only when the diff itself shows the change, and does not speculate about code it cannot see.
Test Coverage & Documentation
Two lighter checks round out a review:
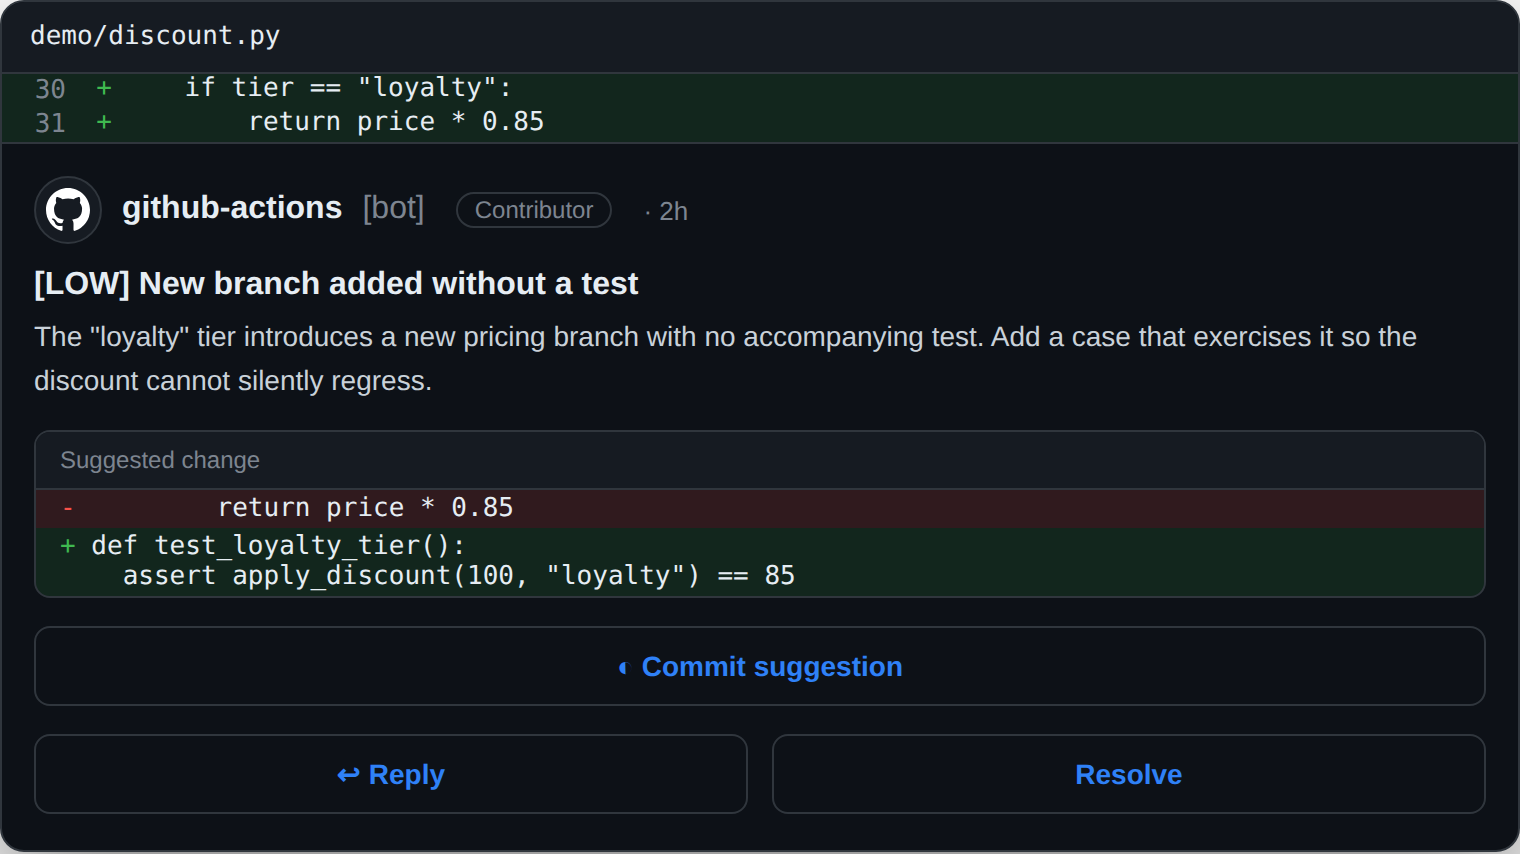
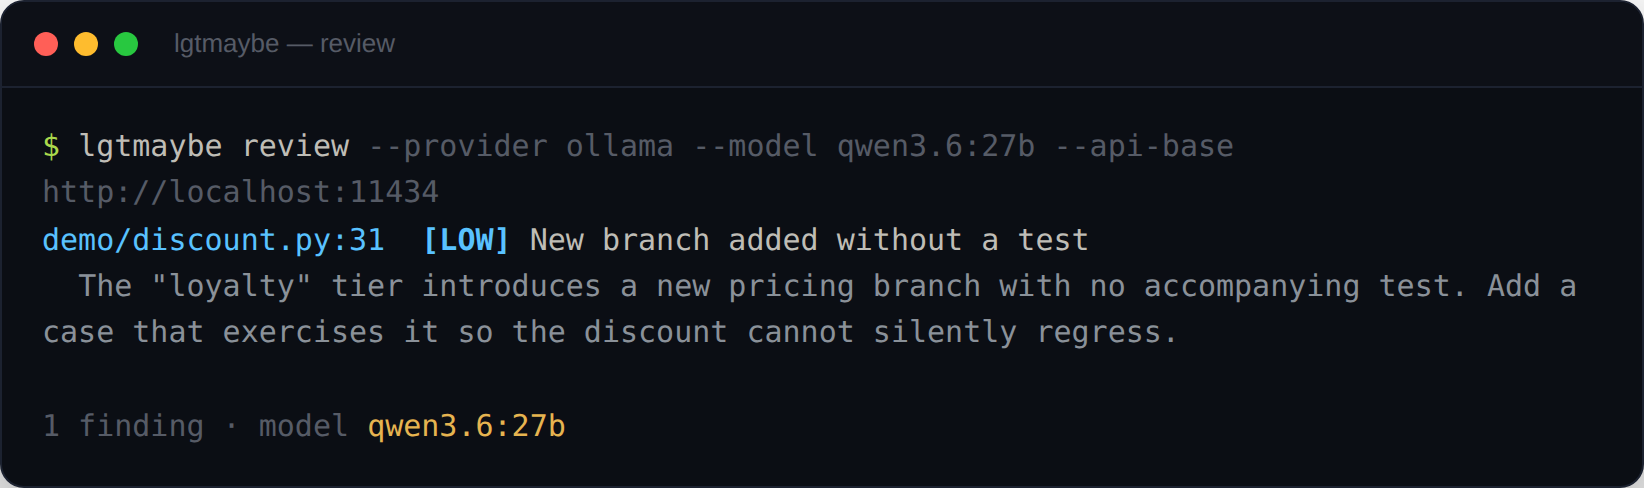
- Missing or weak tests: the diff adds a function, branch, or error case
with no accompanying test. The reviewer raises a
low/mediumfinding. Itssuggestionfield holds a concrete, runnable test in the project's existing test idiom. It also flags tests added in the diff that don't really test anything: assertion-free, mocked until only the mock is exercised, or flaky (sleep-based waits, wall-clock or ordering dependence). It leaves renames, comments, and trivial formatting changes alone. - Documentation gaps and stale docs: a public surface added without a
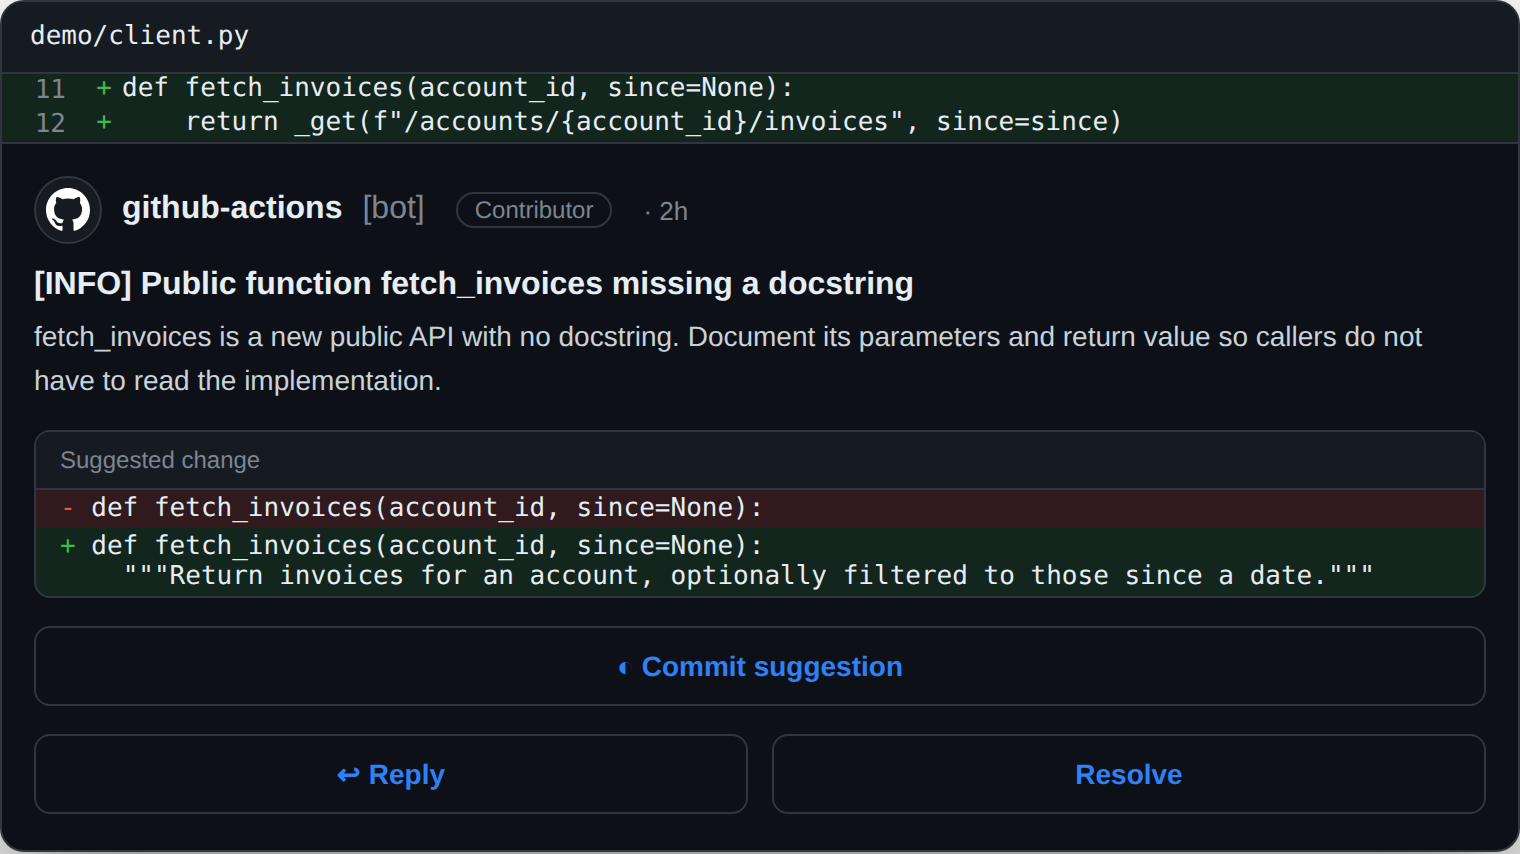
docstring, or a name or signature that contradicts what the code does, is
flagged at
info/low. A docstring or comment the change made wrong is flagged up tomedium, because a comment that lies is worse than none. Private helpers and self-evident code are left alone.
A missing test, with a runnable test in the suggestion:
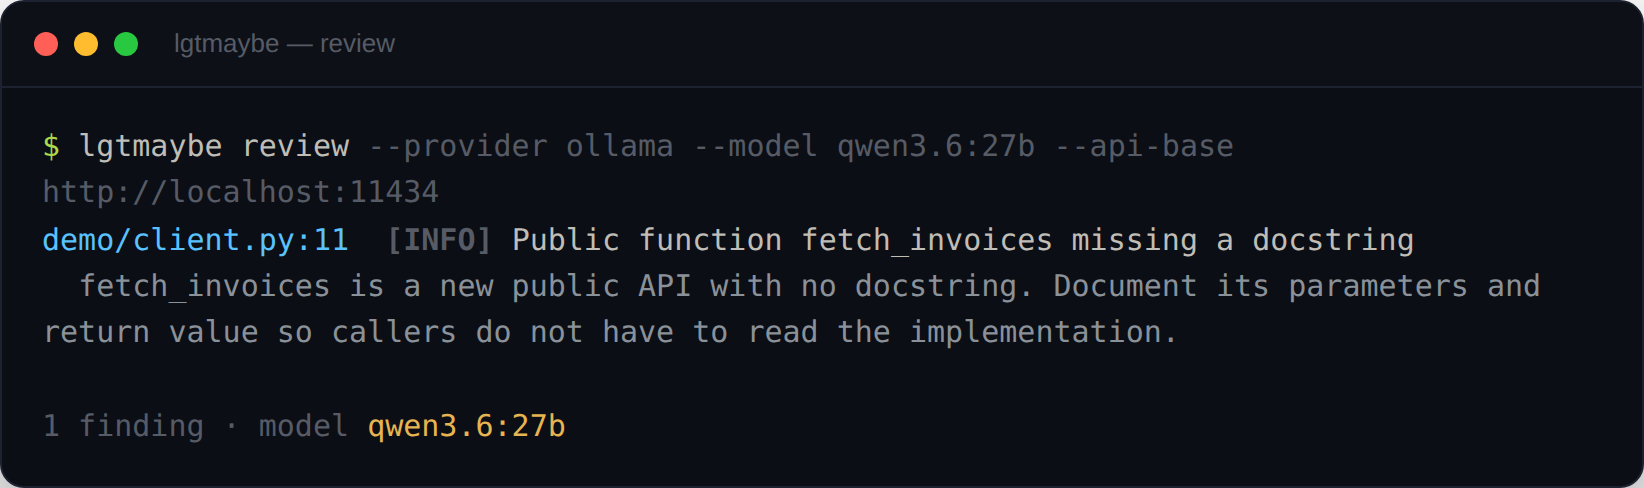
A documentation gap on a new public function:
Performance
The reviewer watches for performance regressions the change introduces, graded
by impact (low, up to high when the cost scales with input size or sits in a
hot path):
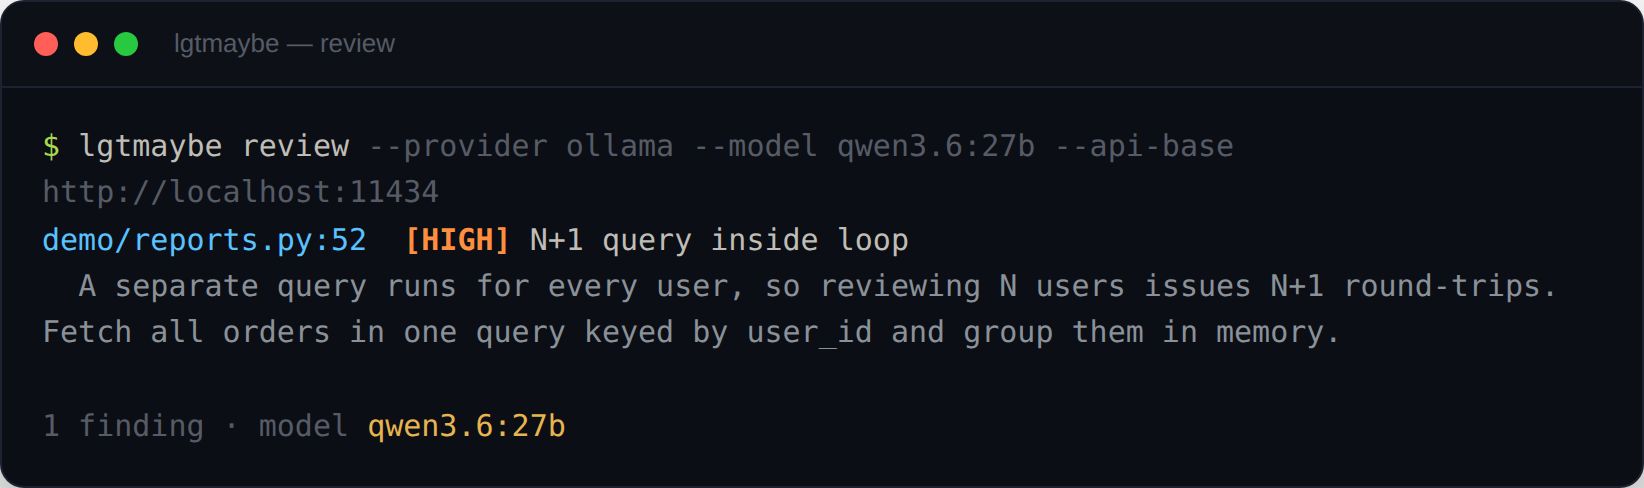
- N+1 queries or calls in a loop: a query, request, or other expensive call issued once per iteration that could be batched or hoisted out.
- Inefficient algorithms: accidentally quadratic (
O(n²)) work where linear is feasible, or a linear scan where a set or dict lookup would do. - Redundant computation: recomputing the same value inside a loop instead of hoisting or memoising it.
- Unnecessary allocations and copies: building large intermediates or copying big buffers on a hot path when streaming or in-place work would do.
- Blocking I/O on a hot path: synchronous I/O, sleeps, or lock contention where non-blocking handling is expected.
- Unbounded or over-fetching queries: loading whole tables into memory, or missing pagination and limits.
- Unbounded growth and leaks: caches without eviction, listeners or subscriptions never removed, queues that only grow.
It sticks to changes the diff shows and skips micro-optimisations with no measurable impact.
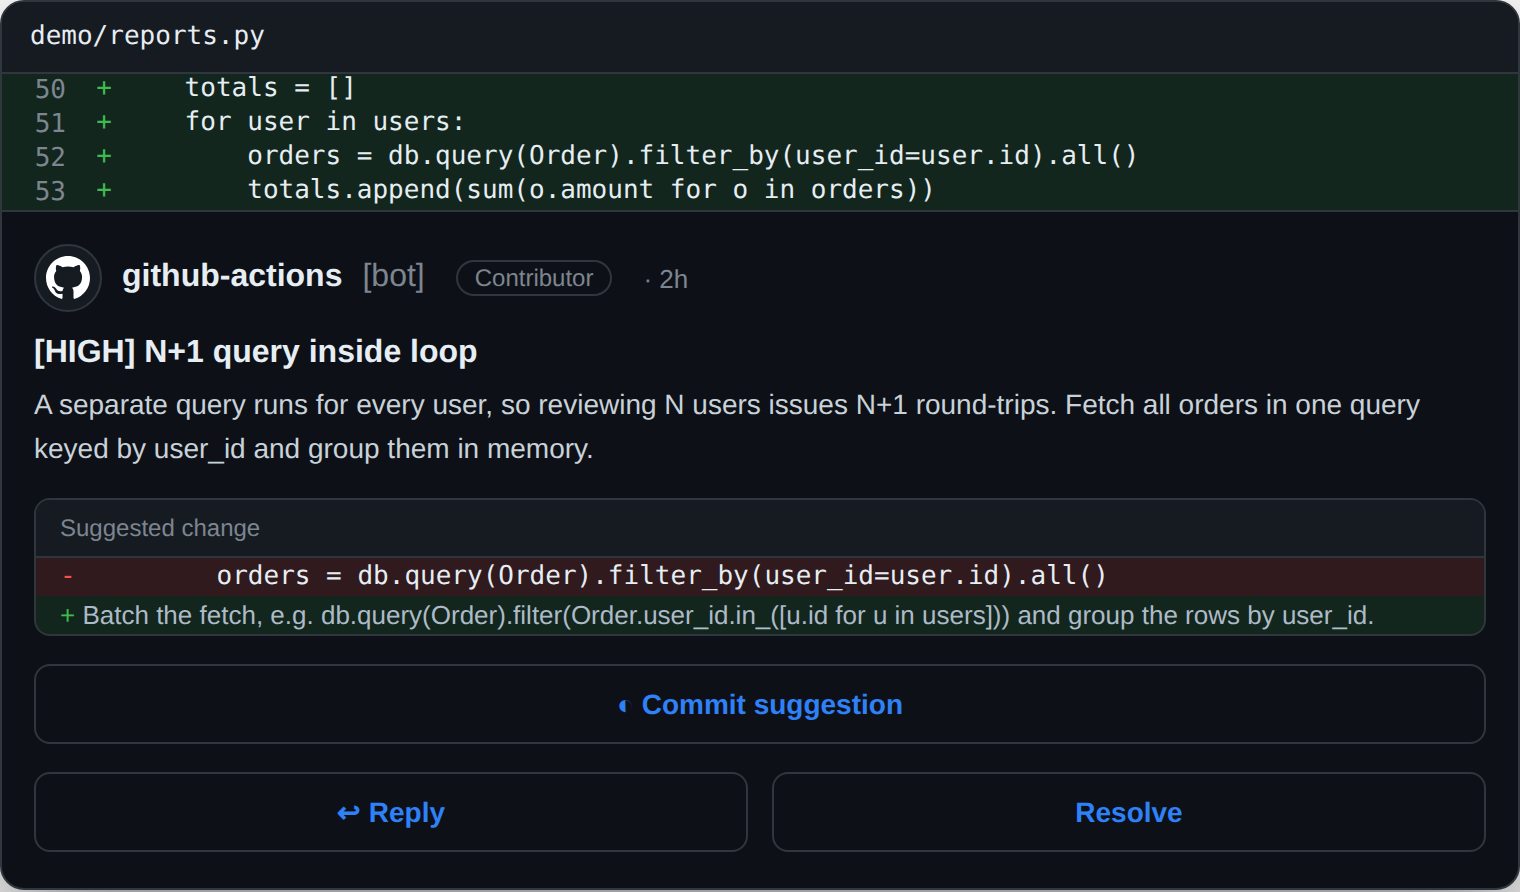
Complexity
A restrained lens that flags code harder to read, test, or maintain than it
needs to be (info/medium), preferring a concrete simplification in the
suggestion field:
- High cyclomatic complexity or deep nesting: many branches, or deeply nested conditionals and loops that would read better with early returns.
- Over-long, low-cohesion functions: a function doing several unrelated things that should be split.
- Duplicated logic: non-trivial logic repeated in the diff that belongs in a shared helper.
- Excessive parameters or boolean-flag arguments, convoluted expressions, and dead or unreachable code.
Like the documentation lens, it stays quiet on code that is already simple.
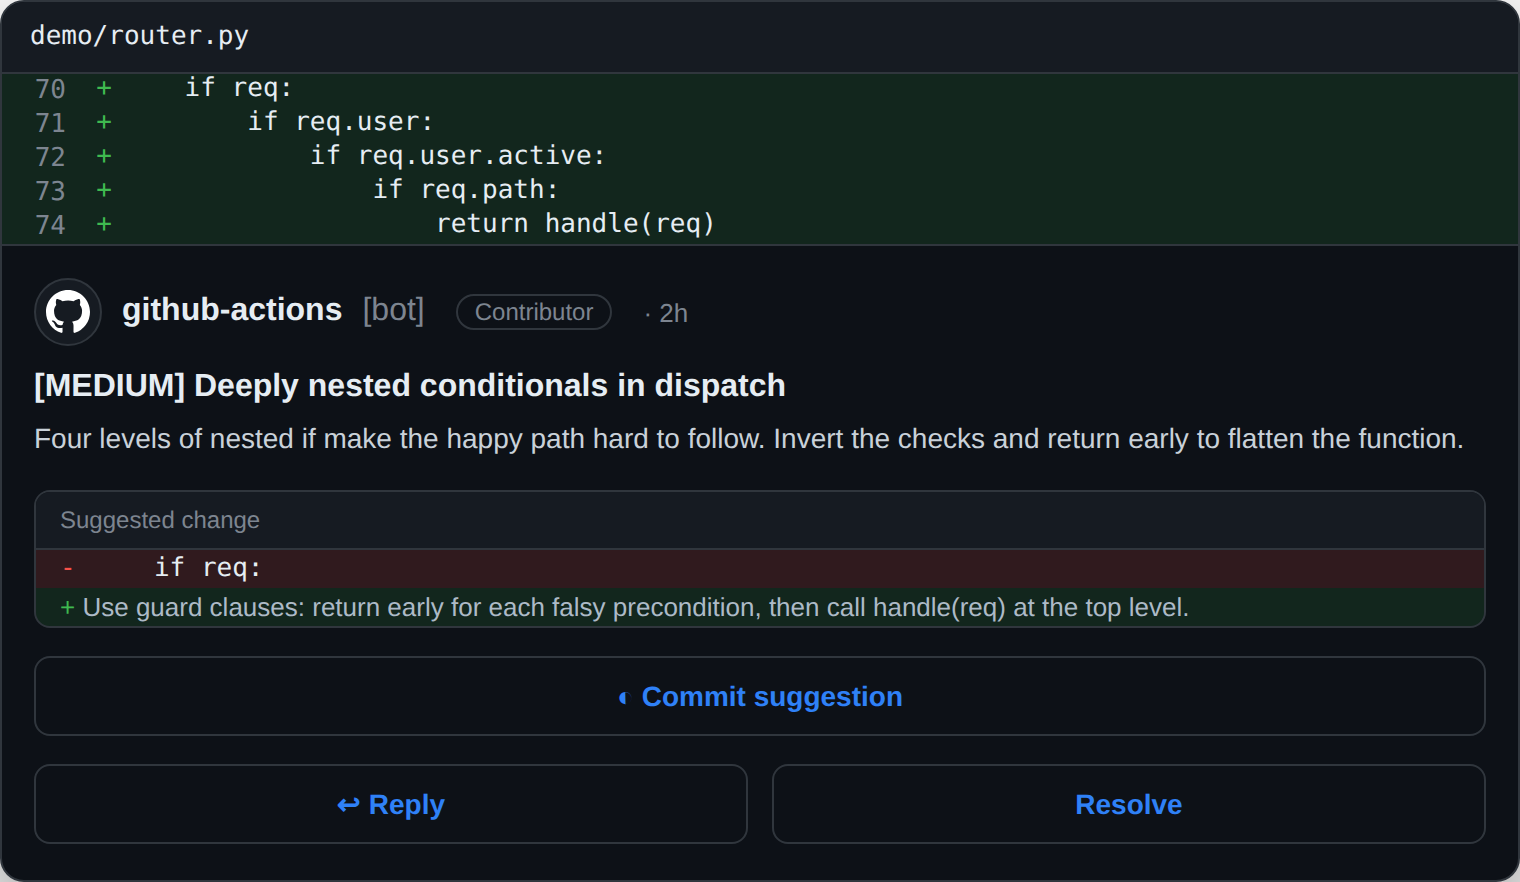
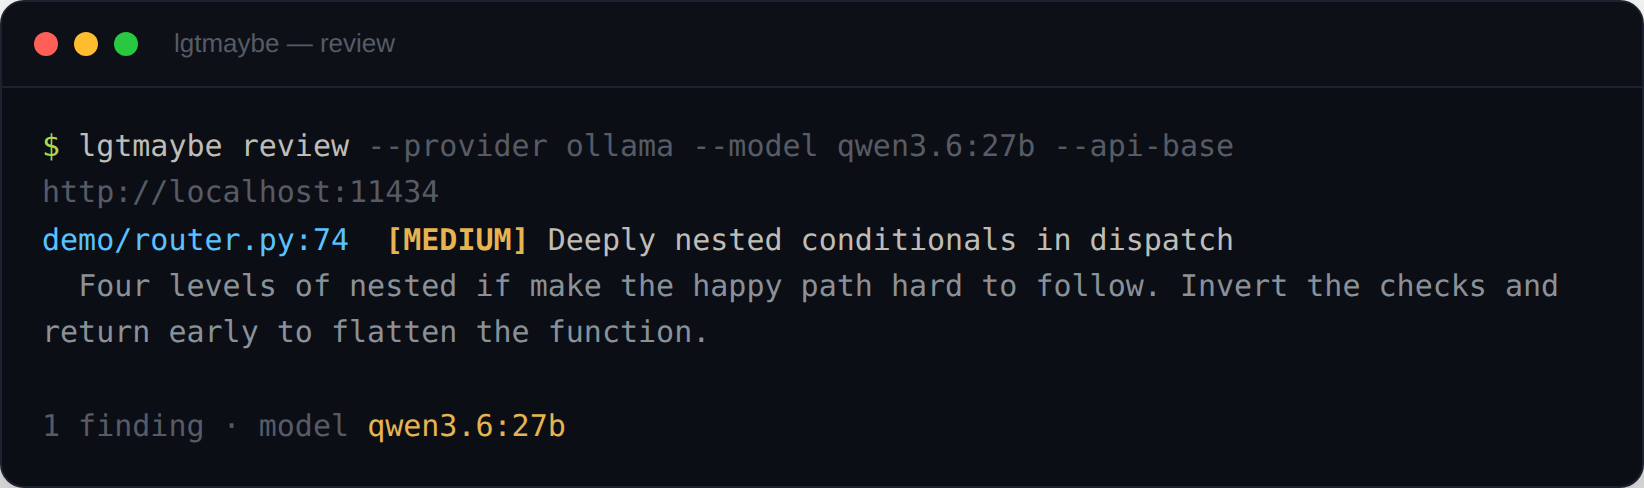
Intent: Does the PR Do What It Says?
The intent lens compares the diff against the PR's stated intent and flags
mismatches at medium, or high when the unexplained change is
security-relevant:
- Out-of-scope changes: a hunk unrelated to the stated intent, such as a "fix typo" PR that also touches auth logic, CI workflows, dependency pins, or permissions. Smuggled security-relevant changes are the most valuable catch.
- Contradictions: the code does the opposite of, or something materially different from, what the title or commits claim.
- Unfulfilled intent: the PR promises behaviour the diff never implements.
Where the stated intent comes from:
- On a GitHub PR: the PR title, description, and the first line of each commit message, fetched via the API.
- On the CLI: the commit subjects from your local
git logagainst the base branch, so the lens works without GitHub, in--workingmode too. With no commits beyond the base yet (or with--uncommitted), nothing states an intent and the lens is skipped.
Under the default fast preset, intent is
folded into the correctness call rather than run as a call of its own.
The Lens Is Told What It Was Not Shown
An intent lens judging "did the author keep their promise?" against a filtered diff will call a kept promise broken. Files go missing for seven reasons:
- the generated/binary/vendored skip;
- your
include_paths/exclude_pathsglobs; - the
max_file_diff_linessize cap; - the
max_filescap; - a triage skip;
- an incremental scope;
- being in another batch. Lenses run once per batch, so on a large PR each call sees only part of the change.
So each call is told which of the PR's files it cannot see. The list goes to every lens. The intent lens also gets the rule that goes with it: a claim about a file that was not shown is not shown, not undone.
lgtmaybe derives the list from what is left of the PR after the batch. It therefore covers every one of those mechanisms without caring which applied. It is capped, then wrapped and neutralised as untrusted data, because filenames are attacker-controlled on a fork PR too. That is why lgtmaybe doesn't report "the stated intent to regenerate X is not reflected in the diff" when X is a generated file it was never allowed to read.
The intent text is attacker-controlled on a fork PR, so lgtmaybe treats it exactly like the diff:
- secrets are redacted;
- it is wrapped as untrusted data with neutralised delimiters;
- the model is told never to follow instructions inside it.
Only the call that carries the intent lens ever sees it. When a PR states no intent at all, the lens is skipped instead of spending a model call.
Spec: Does the PR Deliver the Specification It Commits To?
Your repository may drive its work from a committed specification. That spec is a better statement of intent than a PR description: it is structured, it predates the code, and its task list records what the author claims to have finished. The spec lens checks the diff against it in both directions.
lgtmaybe recognises three layouts out of the box, plus your own:
| Workflow | Detected by | Read |
|---|---|---|
| OpenSpec | openspec/changes/<id>/, openspec/specs/<capability>/ |
proposal, delta specs, design, tasks (archived changes are ignored) |
| GitHub Spec Kit | .specify/, or specs/<slug>/ with a spec.md and a plan.md |
spec, plan, tasks |
| Kiro | .kiro/specs/<feature>/ |
requirements, design, tasks |
| Your own layout | spec_paths globs in .lgtmaybe.yml |
whichever of those filenames are present |
What It Reports
The diff falling short of the spec
- Contradicts an explicit requirement: the code does the opposite of a
stated SHALL/MUST or acceptance criterion (
high). - A ticked task that is not delivered (
medium); see below. - A requirement in scope with nothing implementing it (
medium). - An acceptance criterion with no test (
low).
The spec falling short of the diff: the half people miss, and the more reliable of the two, because the evidence is entirely in the diff.
- Behaviour no requirement covers: a new endpoint, state, error path, limit
or side effect the spec never mentions (
low/info). - A requirement the change made stale (
low). - An unresolved
[NEEDS CLARIFICATION]still sitting in a requirement this PR implements (info).
Ticked Checkboxes Are Claims
All three workflows track progress with markdown checkboxes, and a PR that implements tasks flips them:
-- [ ] T014 [US1] Enforce the 30-day link expiry in src/links/service.py
+- [x] T014 [US1] Enforce the 30-day link expiry in src/links/service.py
That flip is already in the diff. lgtmaybe extracts it with no model call and no extra file read, and hands the lens the list as claims the author made in this pull request. That turns a vague question ("did this deliver the spec?") into a precise one ("is T014 actually here?"). A ticked task is something to check, never to assume false: the lens flags it only when the diff shows the work is absent.
Which Spec, and When It Stays Quiet
A monorepo can hold forty spec directories. lgtmaybe ranks them against the PR on these signals, and sends at most two:
- the PR edits the spec;
- the PR's branch is named after it;
- the PR's title, description or commits name it.
Spec Kit names branches after the spec directory, which is what makes the branch signal work. When nothing matches, the lens does not run at all: no model call, no prompt bytes. The same is true when no spec system is present, which is the common case, so a repository without specs pays nothing.
Because it needs its own large block, the spec lens is a call of its own: a
sixth call under the default fast preset, made only when a spec matched. Turn
it off with --no-spec on the CLI, or spec_review: false in .lgtmaybe.yml
or as an Action input.
The Spec Lens Is Told What It Was Not Shown
A requirement is delivered by code, so this lens is even more exposed than the intent lens to the filtered-diff trap. Told nothing, it reports every requirement implemented in another batch as undelivered. It gets the same correction:
- the list of the PR's files this call cannot see;
- the rule that a requirement delivered in one of them is not shown, not undelivered.
Spec text is treated exactly like the diff: redacted, wrapped as untrusted data in its own neutralised block, and never obeyed. That is deliberate. A spec is usually committed in the same PR that implements it, so on a fork PR the author controls the requirements their own change is judged against.
Files the PR changes are read from its head text for the same reason: the base
branch does not have them yet. Everything else comes from the checked-out
workspace, which on pull_request_target is the trusted base branch. The worst
a planted spec can do is suppress a spec finding, because no other lens sees the
block.
Ponytail: The Laziest Senior Dev in the Room
The best code is the code you never wrote. Inspired by Ponytail 5, this lens reviews new code with a senior engineer's reflex to not add code. It walks Ponytail's ladder and stops at the first rung that holds:
- Does this need to exist?
- Is it already in this codebase?
- Does the standard library or platform do it?
- Does an installed dependency do it?
- Can it be one line?
It flags what skipped a rung (graded info to medium, and deliberately
restrained):
- Needless code (YAGNI): speculative generality, "just in case" parameters, an abstraction with a single caller, or scaffolding for a future that isn't here.
- Re-implementing what exists: a helper this codebase already has (only when that helper is in front of the model), or hand-rolled code that a built-in, the standard library, or an already-imported dependency does directly.
- A new dependency for a few lines: a package added for what a handful of lines or an installed dependency already does.
- Could be far shorter: several lines doing what one clear expression would.
- Premature configurability: flags, hooks, or options no caller uses yet.
It prefers deleting or collapsing code over adding to it, and puts the smaller replacement in the suggestion. It also:
- checks the code really is unused before saying so;
- never collapses an existing port, layer, or interface boundary (an adapter implementing one is not needless);
- treats a
shortcut:comment as a recorded decision rather than a finding.
The complexity lens asks "is this code hard to follow?"; Ponytail asks "should this code exist at all?"
We take Ponytail's leanness rules, not its whole review: Ponytail 5's own
/ponytail-review also checks bugs, security, load, and tests, which here are
separate lenses.
Architecture: What Will This Make Hard to Change?
Architecture is the set of decisions that are expensive to reverse. This lens
flags only decisions the change itself introduces, graded info to medium.
Every finding has to open with a concrete change scenario: "when X changes, Y
and Z have to change with it". A finding that only names a principle ("this
violates SRP") is not allowed, because the name explains nothing on its own.
- Coupling across boundaries: one module reaching into another's internals, long call chains across a package or service boundary, or mutable state shared between modules. Tight coupling inside one module is fine; the same coupling across a boundary, on something likely to change, is the finding.
- Dependencies pointing the wrong way: domain code importing a framework, adapter, database or HTTP client, an import that closes a cycle, or a stable module starting to depend on a volatile one.
- Broken substitutability (Liskov): an override that accepts less than its base class, promises less, raises errors the base never did, or quietly does nothing, and callers that branch on a concrete subclass instead. It only claims this when the base class is in front of it.
- Misplaced responsibility: a module gaining a second, unrelated reason to change, logic that mostly works on another object's data, or one concept spread so a single change needs edits in several places.
- Sharp edges: new public surface that is easy to misuse, such as calls that must happen in a hidden order, internal mutable state handed out, or malformed input accepted silently.
- Leaky ports: an interface that forces implementers to stub methods they don't need, or vendor types crossing a port so the core is tied to the vendor.
Its evidence bar keeps it from becoming a lecture:
- It never proposes a new abstraction unless the diff shows a second implementation or caller, or the coupling crosses a boundary the repository already has.
- It reads layers from the repository's own paths and documented architecture rather than inventing them.
- It skips tests, scripts and private helpers.
- It hedges to
infoorlowwhen the claim depends on code it cannot see.
Most findings carry no one-click suggestion. The finding names a structural fix instead (move the function, invert the dependency).
The ideas come from the classic literature on design:
- Parnas on information hiding;
- Constantine and Yourdon on coupling and cohesion;
- Liskov and Wing on substitutability;
- Meyer on design by contract;
- Martin on dependency direction;
- Cockburn's ports and adapters;
- Evans on bounded contexts;
- Fowler's refactoring catalogue;
- Bloch on API design;
- Khononov on balancing coupling.
See ATTRIBUTION.md.
The complexity lens asks "is this hard to follow?" and ponytail asks "should
this exist?"; architecture asks "what will this make hard to change?". For a
finer grain, the opt-in pack:design adds Ousterhout-style checks such as
shallow modules and information leakage.
When Lenses Disagree
Each lens is prompted on its own and none of them names another. Two lenses could therefore, in principle, give opposite advice about the same lines. One says "cut this", another says "this guard is what keeps it safe". Posting both tells the author two contradictory things, so lgtmaybe stops it at four points:
-
Nobody cuts protective code. A rule shared by every lens covers bundled packs and your own custom lenses too. It forbids recommending the removal or weakening of:
- validation at a trust boundary;
- error handling that prevents data loss;
- security controls;
- accessibility support.
Any shorter replacement must keep every edge case and error path. This is Ponytail 5's "never cut" list, applied to all of them.
-
Each lens has its own evidence bar. The bars keep territories apart without lenses knowing about each other:
- ponytail never collapses an existing boundary;
- architecture never proposes a new one without a visible second implementation;
- complexity only suggests extracting duplicated code when the copies have uniform callers (never through a flag argument).
-
Reflection referees. The self-reflection pass sees every finding at once. When two give opposite advice about the same code, it keeps the one higher on the ladder: correctness, security, performance, tests, architecture, complexity, ponytail. That is Ponytail 5's own review order (correctness, safety, load, tests, speed, leanness) mapped onto these lenses, with design slotted above readability. A finding whose lens is not on the ladder, such as a custom or pack lens, is never arbitrated.
-
A deterministic backstop. After reflection (and even with
--no-reflect),engine/conflicts.pydrops a lower-ranked finding when:- it sits within three lines of a higher-ranked one; and
- the two come from a lens pair declared opposed. Today that is ponytail against correctness, security, and architecture.
Group ids, custom and pack lenses, and scanner hits declare no opposition, so the backstop never guesses about them. It sees only where a finding sits, not what it advises. That is why it acts only on pairs that oppose each other by nature. Reflection reads the advice itself, so it covers the rest of the ladder. It drops one of two findings only when they really do point opposite ways.
The counter-advice eval fixture measures this. It plants a genuine lean catch
beside two traps: upload validation that looks redundant, and an adapter that
looks like a pass-through. The run fails if a model recommends cutting either.
How the Scope Is Bounded
Every run is bounded so a large PR can't run away on latency. All of these are
configurable in .lgtmaybe.yml (see
Configure .lgtmaybe.yml):
| Knob | Default | Effect |
|---|---|---|
preset |
fast |
fast uses five calls (security, correctness, code health, artefacts, architecture) on every provider, plus a sixth spec call when a spec matches; full runs one call per lens. |
max_files |
50 | Reviews the top-N changed files and posts a "reviewed top N of M" notice if there are more. |
max_file_diff_lines |
2000 | Skips any single file whose diff is longer, naming it in the summary. 0 disables. |
max_input_tokens |
100,000 | Batches the diff so each model call stays within budget. Left at the default, it is capped at what the model's context window can take. |
max_concurrency |
6, every provider | Concurrent model calls across the whole fan-out (all batches share one pool). Local throughput is set on the server (OLLAMA_NUM_PARALLEL, llama.cpp -np, vLLM batching); set this to 1 for serial. |
max_review_seconds |
3600 | Soft wall-clock ceiling: past it, queued calls are skipped and the review posts partial results with a notice. 0 disables. |
categories |
all | Which review lenses run (the ten everyday lenses, plus spec when a spec matches). An explicit list overrides the preset grouping and runs each listed lens as its own call. |
context_lines |
20 | Ceiling on surrounding lines added around each hunk; the budget may use fewer. 0 disables context expansion. |
min_severity |
low (medium for a prototype project) |
Drops findings below the floor (info → low → medium → high → critical). low keeps everything except pure-info narration. |
include_paths / exclude_paths |
none | Glob filters to focus the review. |
These bound a single run, not the number of runs. On a public repo, anyone who can open a PR or comment can trigger a run, and each run calls your chosen LLM provider. See the cost disclaimer in Use as a GitHub Action.
What a Finding Contains
Every finding is written for an engineer new to the codebase. Its title leads with the fix when one is known. Its body says what goes wrong and why it matters, in plain words, and explains a technical term the first time it appears. The change overview comment follows the same rule.
Findings are structured data, not prose, so they render the same everywhere. Each finding has:
| Field | Meaning |
|---|---|
path |
File the comment attaches to |
line |
Line in the diff |
side |
RIGHT (added/changed) or LEFT (removed) |
severity |
info / low / medium / high / critical |
title |
One-line summary |
body |
The explanation |
failure_scenario |
For defect findings: the trigger, the changed behaviour, and the observable impact |
suggestion |
Optional suggested replacement code |
anchor |
The flagged line, verbatim, used to place the comment on the right line |
anchored |
Whether anchor matched a changed line; an unanchored finding moves to the review body |
broad |
Set by reflection when the fix needs a broad change (redesign, infra, API contract) rather than a local edit; broad findings go to a collapsed "Broader observations" section |
category |
The lens that raised it |
confidence |
The self-reflection auditor's 0-10 score (absent when reflection is off) |
The ten everyday review categories are security, correctness, deprecation,
tests, documentation, performance, complexity, intent, ponytail, and
architecture. spec is an eleventh that runs only when a committed spec matches
the PR. The default fast preset covers the ten in five calls, one per concern:
- security;
- correctness (with stated intent folded in);
- code health (performance, complexity, ponytail, deprecation);
- artefacts (tests, documentation);
- architecture.
The same five run on every provider; worker count changes only how they are
scheduled. preset: full runs each category as its own call, with a worked
example of its own finding type.
lgtmaybe drops two kinds of finding:
- security, correctness, deprecation, and performance findings without a
concrete
failure_scenario; fastcode-health findings the model left unattributed (any of them may be a performance or deprecation one).
It merges and de-duplicates the rest. A self-reflection pass then audits the rest and drops low-confidence findings. So the model's first guesses are filtered before anything is posted.
The reviewer only sees the diff and some surrounding context: a slice of the codebase, not the whole thing. A concern may depend on code it can't see, such as a guard, a base class, or an idempotency check that may live in an unshown file. Then it hedges and lowers the severity rather than asserting the thing is missing. The self-reflection pass drops findings that rest on such assumptions. Genuine gaps in the diff itself are exempt and still raised, such as a changed path with no test or a new public surface left undocumented.
What the Response Looks Like
On a Pull or Merge Request
The rendering below is GitHub's. GitLab, Gitea and Azure DevOps show the same findings with the same badges; how each host posts them differs, and is covered at the end of this section.
lgtmaybe posts one review containing:
- an inline comment on the exact changed line for each finding, and
- a summary that names the model used.
Each finding lands on the line that triggered it. Its severity is in the title and the explanation in the body. Where the fix is clear, it adds a suggested change you can commit straight from the PR.
A finding the engine could not place on a changed line is listed in the summary
instead of posted on a guessed line. It is listed only when it is serious enough
(unanchored_min_severity, default high).
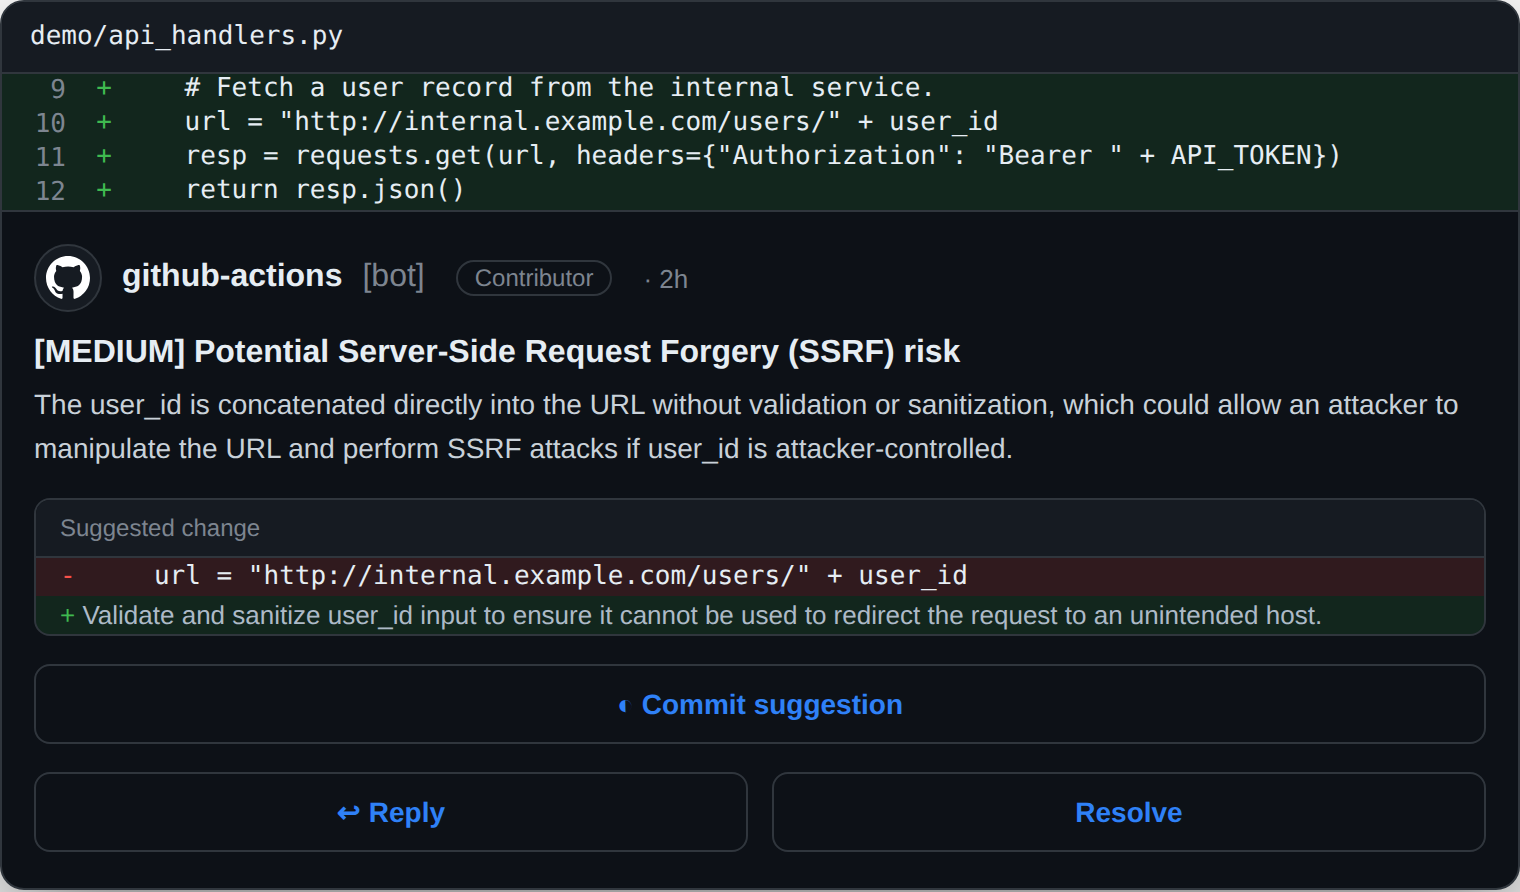
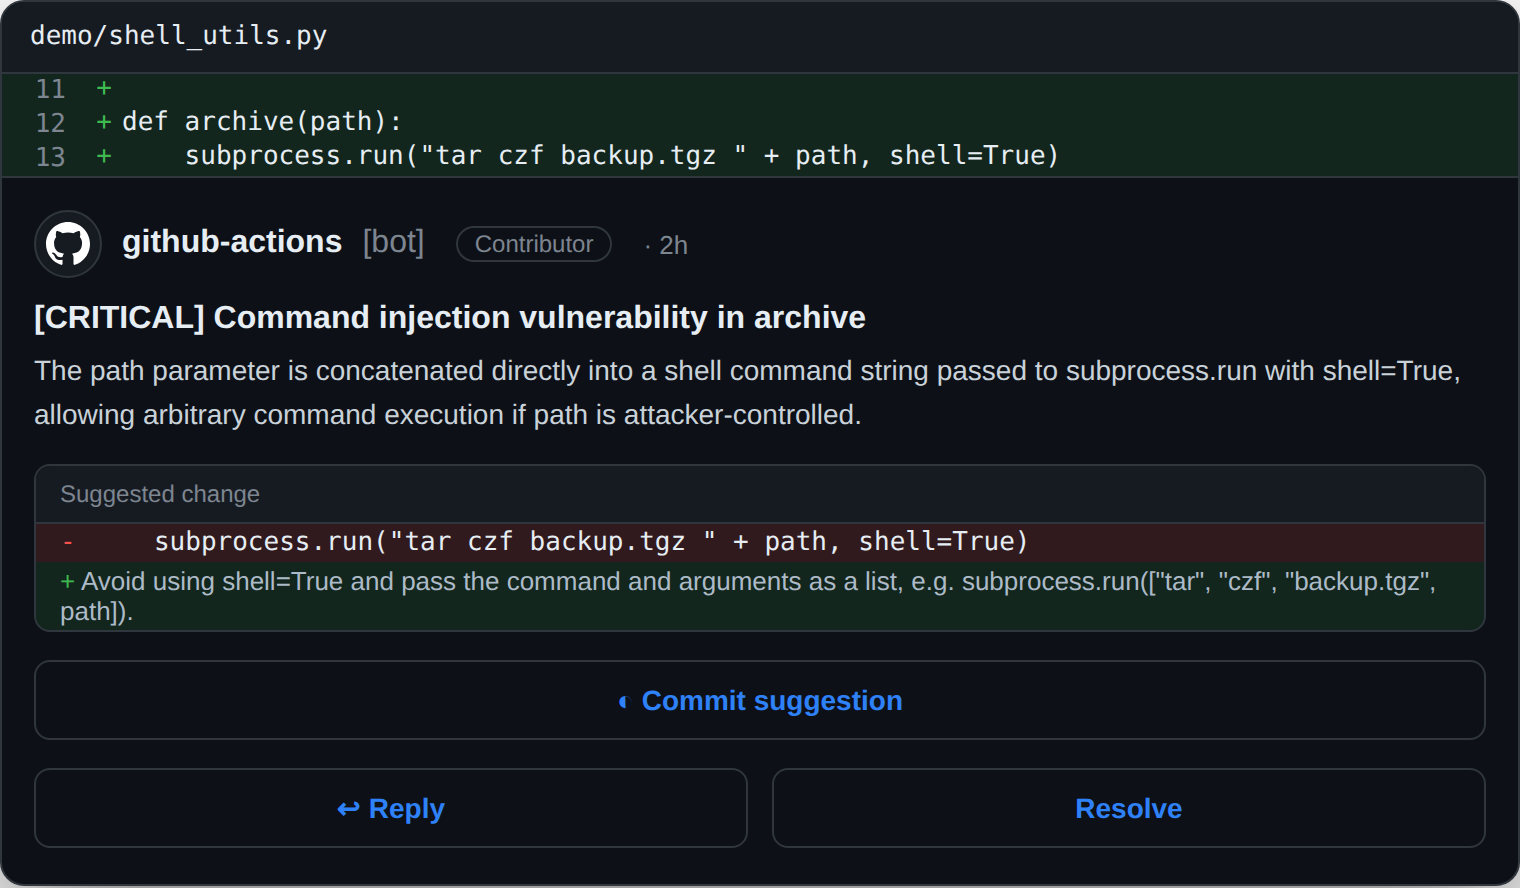
The summary carries a hidden marker (<!-- lgtmaybe -->). Re-running at the
same commit updates that summary instead of creating a duplicate. A
completed review at a new commit posts a fresh summary and leaves the older one
as history. Findings already posted are never posted twice.
Reading the Title Line
A comment's title line carries the finding's provenance in its brackets:
**[HIGH · security · 80%] User input is concatenated into the SQL string**
HIGHis the severity.securityis the lens that raised it: one of the review categories (or your own id if you added a custom lens). It is the same value you match on infinding_rules, so a badge you keep seeing and don't want tells you exactly which rule to write.80%is the self-reflection auditor's confidence that the finding is real, reached by trying to disprove it. It is the auditor's 0-10 score shown as a percentage, somin_confidence: 5is the same floor as50%. Set that floor to drop everything below a score you choose.
Each part drops away when it isn't there: with reflect: false there is no
score, and the badge is the lens alone.
Neither GitHub's nor Gitea's review API can edit an inline comment once it is posted. So an inline comment's score is frozen at first post: a later run that judges the same finding differently won't change it. Findings in the summary body (the "Additional findings" and "Broader observations" sections) are rewritten on every run, so those badges do track. Severity and title have always behaved this way; the badge makes it visible.
Resolving Conversations Once They're Fixed
Each inline comment also carries hidden per-finding ids. When you push a fix and lgtmaybe runs again, it checks its own open conversations. lgtmaybe treats a finding as fixed when both of these hold:
- the finding it raised is no longer produced;
- GitHub marks that thread outdated (the code under it changed).
It then replies ✅ Looks resolved. and resolves the conversation. Because both
conditions must hold, a thread is never collapsed only because the lines around
it shifted. Nor is it collapsed because one run happened not to re-flag it
while the code stayed the same.
This is on by default. To leave conversations for manual resolution, set
resolve_fixed: false in .lgtmaybe.yml (or the Action's resolve_fixed
input). Resolving a thread uses GitHub's GraphQL API; the workflow's default
GITHUB_TOKEN (with pull-requests: write, already needed to post the review)
is enough. The step is best-effort: if it can't run, the review still posts
normally.
On GitLab the same thing happens over plain REST. On Azure DevOps the thread is set to Resolved. Azure DevOps has no "outdated" flag, so lgtmaybe records the iteration each finding thread was posted at and compares the file then against the file now. It only resolves threads its own token opened, and only after a complete run. Gitea 1.26 or later works the same way: lgtmaybe compares the file at the comment's commit against the file now, then resolves the comment. Gitea cannot reply in a review thread, so no reply is posted. Forgejo and older Gitea have no resolve endpoint, so their comments stay open.
How Each Host Posts
The findings are identical everywhere. What each host's API allows is not:
| GitHub | GitLab | Gitea | Azure DevOps | |
|---|---|---|---|---|
| Inline comments | one batched review | one discussion per finding | one batched review | one thread per finding |
| Summary | the review body, edited in place | a note, edited in place | an issue comment, edited in place | a general thread, edited in place |
| Avoiding duplicates on a re-run | skips ids already posted | skips ids already posted | skips ids already posted | skips ids it posted itself, once the token's identity is known |
| Auto-resolve a fixed finding | ✅ GraphQL | ✅ REST | ✗ no API | ✅ REST |
| Incremental review of new commits | ✅ | ✅ | ✗ no compare diff | not yet |
| Learn from 👎 on a finding | ✅ reactions | ✅ award emoji | ✗ | not yet |
A submitted Gitea review can't be edited, so its summary moves to an ordinary comment and duplicate findings are filtered before posting. GitLab has no batched review object, so each finding becomes its own positioned discussion. Azure DevOps serves no diff at all, so lgtmaybe builds one from the file contents before and after the change, and each finding becomes its own positioned thread.
When a PR is clean (no findings, and every file was within the caps), the summary is short:
👍 LGTM!

0 findings · risk low (no risk signals) · provider anthropic · model claude-sonnet-4-6 · lgtmaybe 2.11.1
The risk segment comes from the risk of change assessment
and is absent when that is turned off (--no-risk, or risk.enabled: false).
If the file cap kicked in, the summary says so (for example "Reviewed the top 50
of 120 changed files"). lgtmaybe never fails
silently: any error is posted back to the PR as a short comment.
On the Command Line
lgtmaybe review runs the same pipeline over your local git diff and prints
the findings. It posts nothing and needs no GitHub token. By default it diffs
the current branch against the remote primary branch (origin/HEAD, falling
back to origin/main/origin/master, then a local main/master). An empty
diff makes no model call; when none of those branches exists it exits non-zero
and asks for --base.
--workingreviews the whole worktree (branch commits plus uncommitted edits) against that same base.--uncommittedreviews only the uncommitted edits againstHEAD.--base <ref>picks a different base.
Both worktree modes include files you haven't git added yet. A brand-new file
is often the one you most want a second pair of eyes on. Anything .gitignore
excludes stays out. The default output is a readable listing
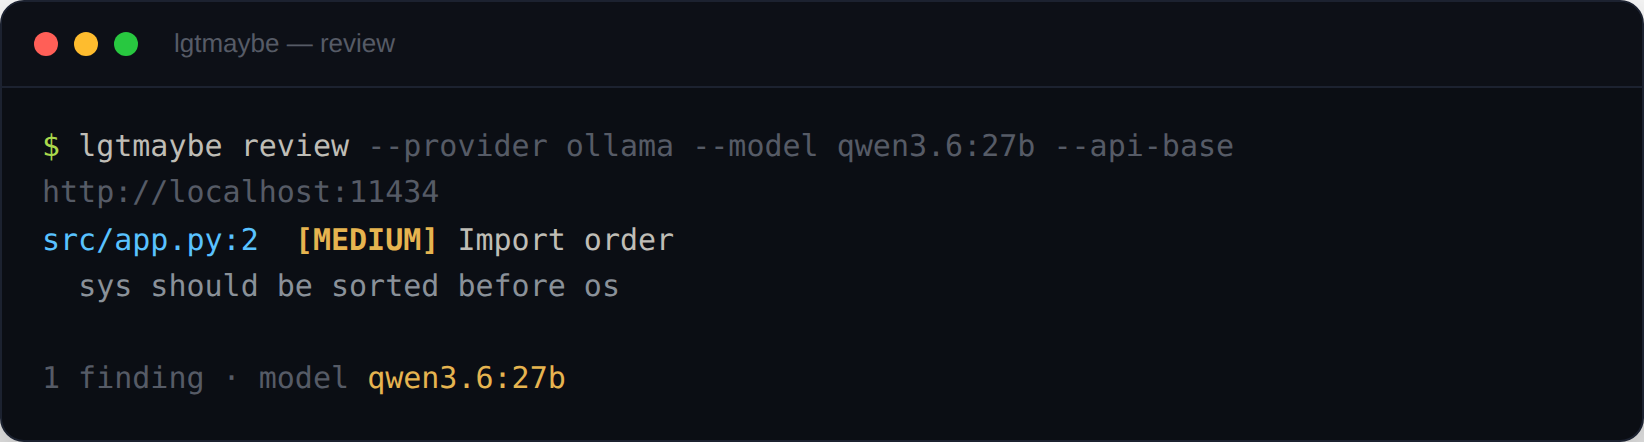
followed by the summary line:
$ lgtmaybe review --provider ollama --model qwen3.6:27b --api-base http://localhost:11434
src/app.py:2  [MEDIUM] Import order (confidence 6/10)
  sys should be sorted before os

1 finding · risk low (no risk signals) · provider ollama · model qwen3.6:27b · lgtmaybe 2.11.1
--format selects the output. --json is shorthand for --format json, which
prints the findings as a JSON array (every field in the table above) so the same
structured data can be piped into other tooling:
$ lgtmaybe review --provider ollama --model qwen3.6:27b --api-base http://localhost:11434 --json
[{"path": "src/app.py", "line": 2, "side": "RIGHT", "severity": "medium",
  "title": "Import order", "body": "sys should be sorted before os",
  "failure_scenario": null, "suggestion": null, "anchor": "import sys",
  "anchored": true, "broad": false, "confidence": 6, "category": "complexity"}]
--format agent turns the findings into plain correction instructions an AI
coding agent can read and apply, for a local review-and-fix loop. See
Fix findings with an AI agent.
lgtmaybe mcp serves both shapes to a coding agent as MCP tool calls; see
Use from a coding agent over MCP.
--format sarif prints a SARIF 2.1.0 log for GitHub code scanning or an IDE
SARIF viewer. The log has:
- one rule per lens;
- the severity folded onto SARIF's three levels;
- the finding's fingerprint and identity as
partialFingerprints.
See Also
- Getting Started: run your first review
- Architecture: the review pipeline, stage by stage
- Data and Privacy: what is sent where